With Strands Decider 2B, the Strands laboratory associated with AWS introduces a small open model specialized in one precise action: selecting an option and expressing a confidence level. This approach promises agents that are faster and less costly than those that rely on a large model for every decision, though it does not eliminate uncertainty or the need to verify choices.
Separating Roles in AI Agents
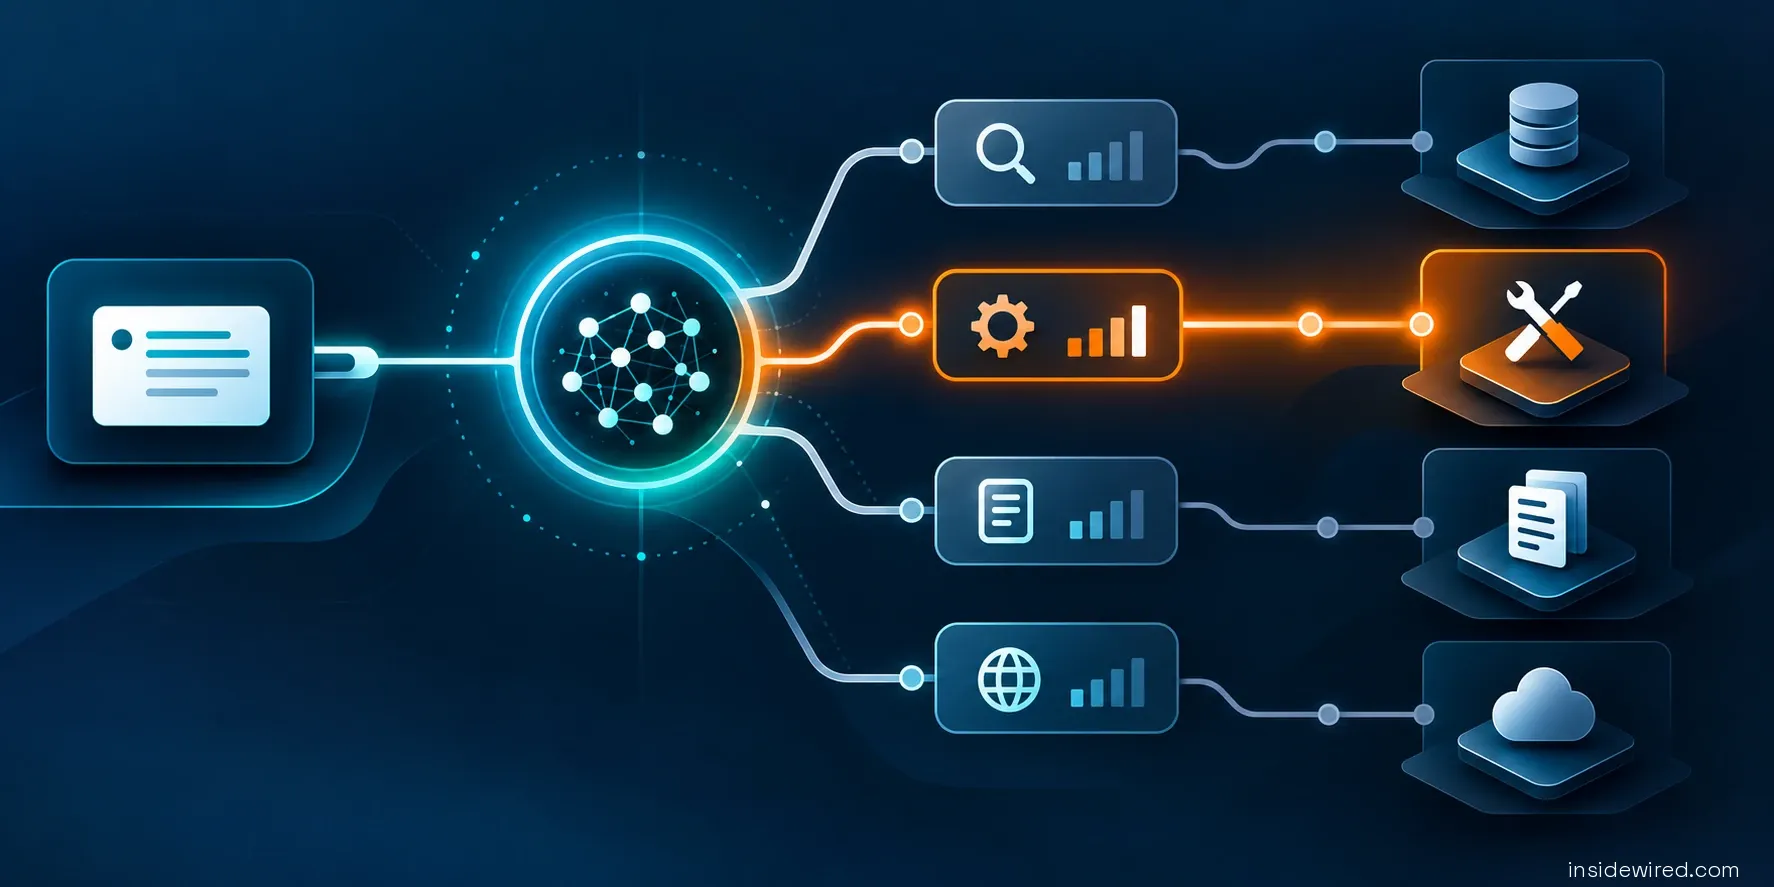
Artificial intelligence agents spend a significant amount of time deciding what to do next. Must they call a search engine, ask for confirmation, execute code, or terminate the task? Currently, these complex decision points are often entrusted entirely to the same large model that also generates the response. Strands Decider 2B proposes separating these roles: a compact model chooses from predefined actions, while more substantial systems intervene only when necessary.
The model utilizes approximately two billion parameters and is built upon Qwen3.5-2B. Its expected output is not an essay; rather, it must compare several options, select one, and provide a confidence level. This strict constraint makes it easier to integrate into an orchestrator. A company can define specific actions—such as "reply," "search," "hand off to human," or "refuse"—and use the model as a sophisticated router for those choices. The decision process becomes faster, less costly, and potentially executable on a local machine.
This concept is part of a broader wave of "decision models," notably popularized by Jev. Their promise is to replace extensive textual reasoning with targeted evaluation. Its connection to William Stanley Jevons, whose work influenced logic and economics, provides an identity for this emerging category. The rapid increase in such offerings highlights that orchestration itself has become a major market—when an agent calls multiple models and tools, choosing the right path can cost nearly as much as generating the response itself.
Efficiency and Architecture Design
The economic gain offered by specialized decision-making is credible. A two-billion-parameter model requires less memory and offers lower latency compared to a massive generalist model. At scale, avoiding a costly call for every fork drastically reduces operational bills and allows teams to conduct more reactive experiments. Furthermore, local execution can help limit sending proprietary data to external services. These advantages are especially useful for customer assistants, documentation pipelines, and embedded systems that repeat a small number of required choices.
However, specialization introduces dependency on the quality of the available options. If the designer forgets an essential action—such as "ask for more information"—the model will be forced to choose among inadequate responses. Similarly, if tool descriptions are ambiguous, it might select a dangerous function with high confidence. The Decider does not correct poor agent design; it merely makes that underlying design process more explicit. This represents progress only if the possible choices, their potential consequences, and necessary permissions are carefully defined.
Evaluating Confidence Scores
The model's reported confidence score requires particular attention. A probability is only truly useful if it is calibrated: out of one hundred reported decisions at an 80% confidence level, approximately eighty should be correct. A model can appear highly confident even when this figure does not match reality, especially when operating outside its initial training data. Therefore, integrators will need to measure calibration on their specific tasks and set appropriate thresholds. Below a certain level, the agent may be configured to request intervention from a more powerful model or a human operator.
The open nature of Strands Decider 2B facilitates this thorough evaluation. Teams can host it, observe its outputs, adapt it, and compare its behavior against deterministic rules. However, "open" does not automatically mean transparent: the training data, inherent biases, and functional limitations of the model can remain difficult to fully understand. Reproducibility also depends on managing multiple components, including the weights, the license, the inference code, and robust benchmarks reflecting real-world situations.
Building Robust Agent Logic
Sometimes, a classic rule set is superior. If a document exceeds a known size threshold, a simple binary check may be enough to select a tool; introducing an additional model increases complexity unnecessarily. The Decider model truly makes sense when the context is nuanced, if the formulations vary greatly, and if multiple distinct signals must be combined for a decision.
The most robust architecture will likely mix structured rules, specialized models, and escalation to a large model, rather than attempting to replace all agent logic with a single probabilistic layer.
Amazon and Strands Labs position themselves at a strategic point in this industry chain. The value of AI agents no longer depends solely on the model that writes; instead, it hinges upon the one that allocates resources, avoids unnecessary calls, and knows when to yield control. If Decider 2B lives up to its promises of speed and cost efficiency, it can make existing agent frameworks more effective without needing to improve their linguistic eloquence. Its success will be measured by sober indicators: routing accuracy, critical errors, calibration, latency, and overall cost per completed task.
The race among Strands, Jev-inspired systems, and future decision models will favor the solution that integrates easily, can be audited rigorously, and correctly determines when it should not decide alone. While choosing quickly is useful in a reliable agent, selecting with deceptive confidence can accelerate a damaging action. Before replacing a large model entirely with Decider 2B, teams must publish their baseline bad routing rates and escalation thresholds: true efficiency begins when the decision remains verifiable.